Sneo
Run models bigger than your GPU.A local LLM engine for Windows and NVIDIA cards. It keeps the experts a model calls most in VRAM, the rest in RAM, and has the GPU and the CPU share every token.One RTX 3090, one 70.6 GB model
Writing code
Reading a 23,847 token prompt
First token on a short chat
Model on 24 GB of VRAM and 32 GB of RAM
Writing speed
Tokens per second while answering, higher is betterReading speed
Prompt tokens per second, higher is betterTime to first token
Seconds until the answer starts, lower is betterMeasured on Nov 12, 2026 on the main test PC: RTX 3090 24 GB, Intel i9-12900K, 32 GB DDR5, Windows 10. Qwen3.8-Flash-Next IQ3_XXS, 64K context window, thinking on, temperature 0.6, up to 256 output tokens, four runs per test, averaged.
Side by side with other engines
Against Strata, on the same 70.6 GB model
Sneo writes faster at every prompt size, from 9% on code to 32% on short chats, and starts answering sooner on code reviews and long prompts. Strata still starts sooner on short chats and, by 5%, on very long prompts.
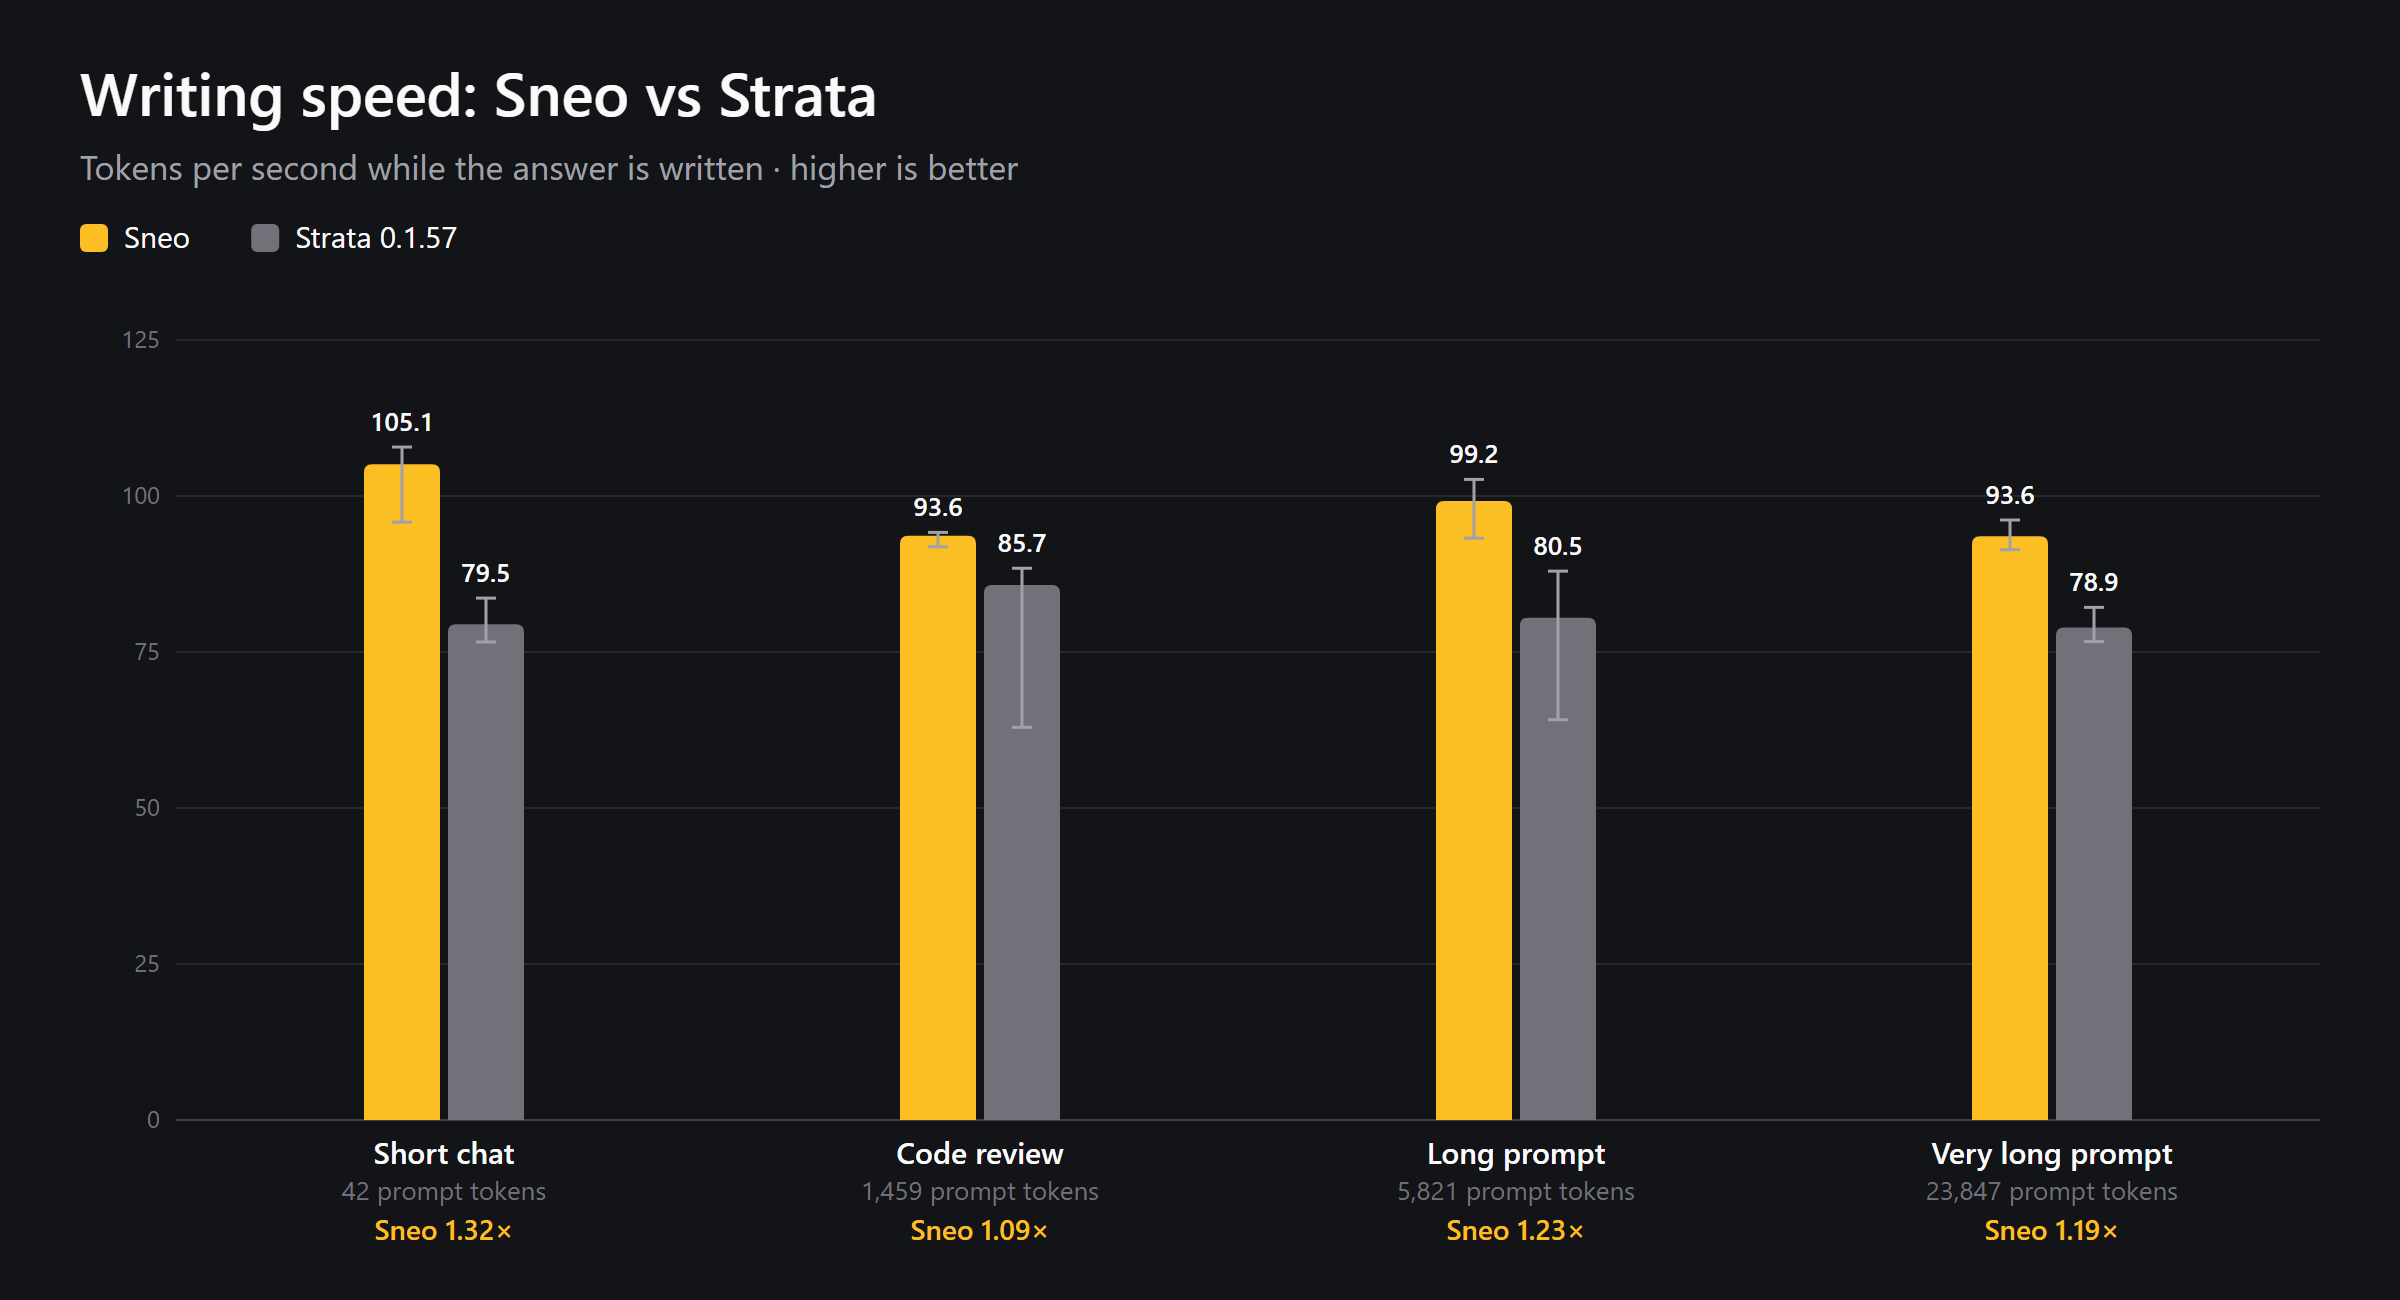
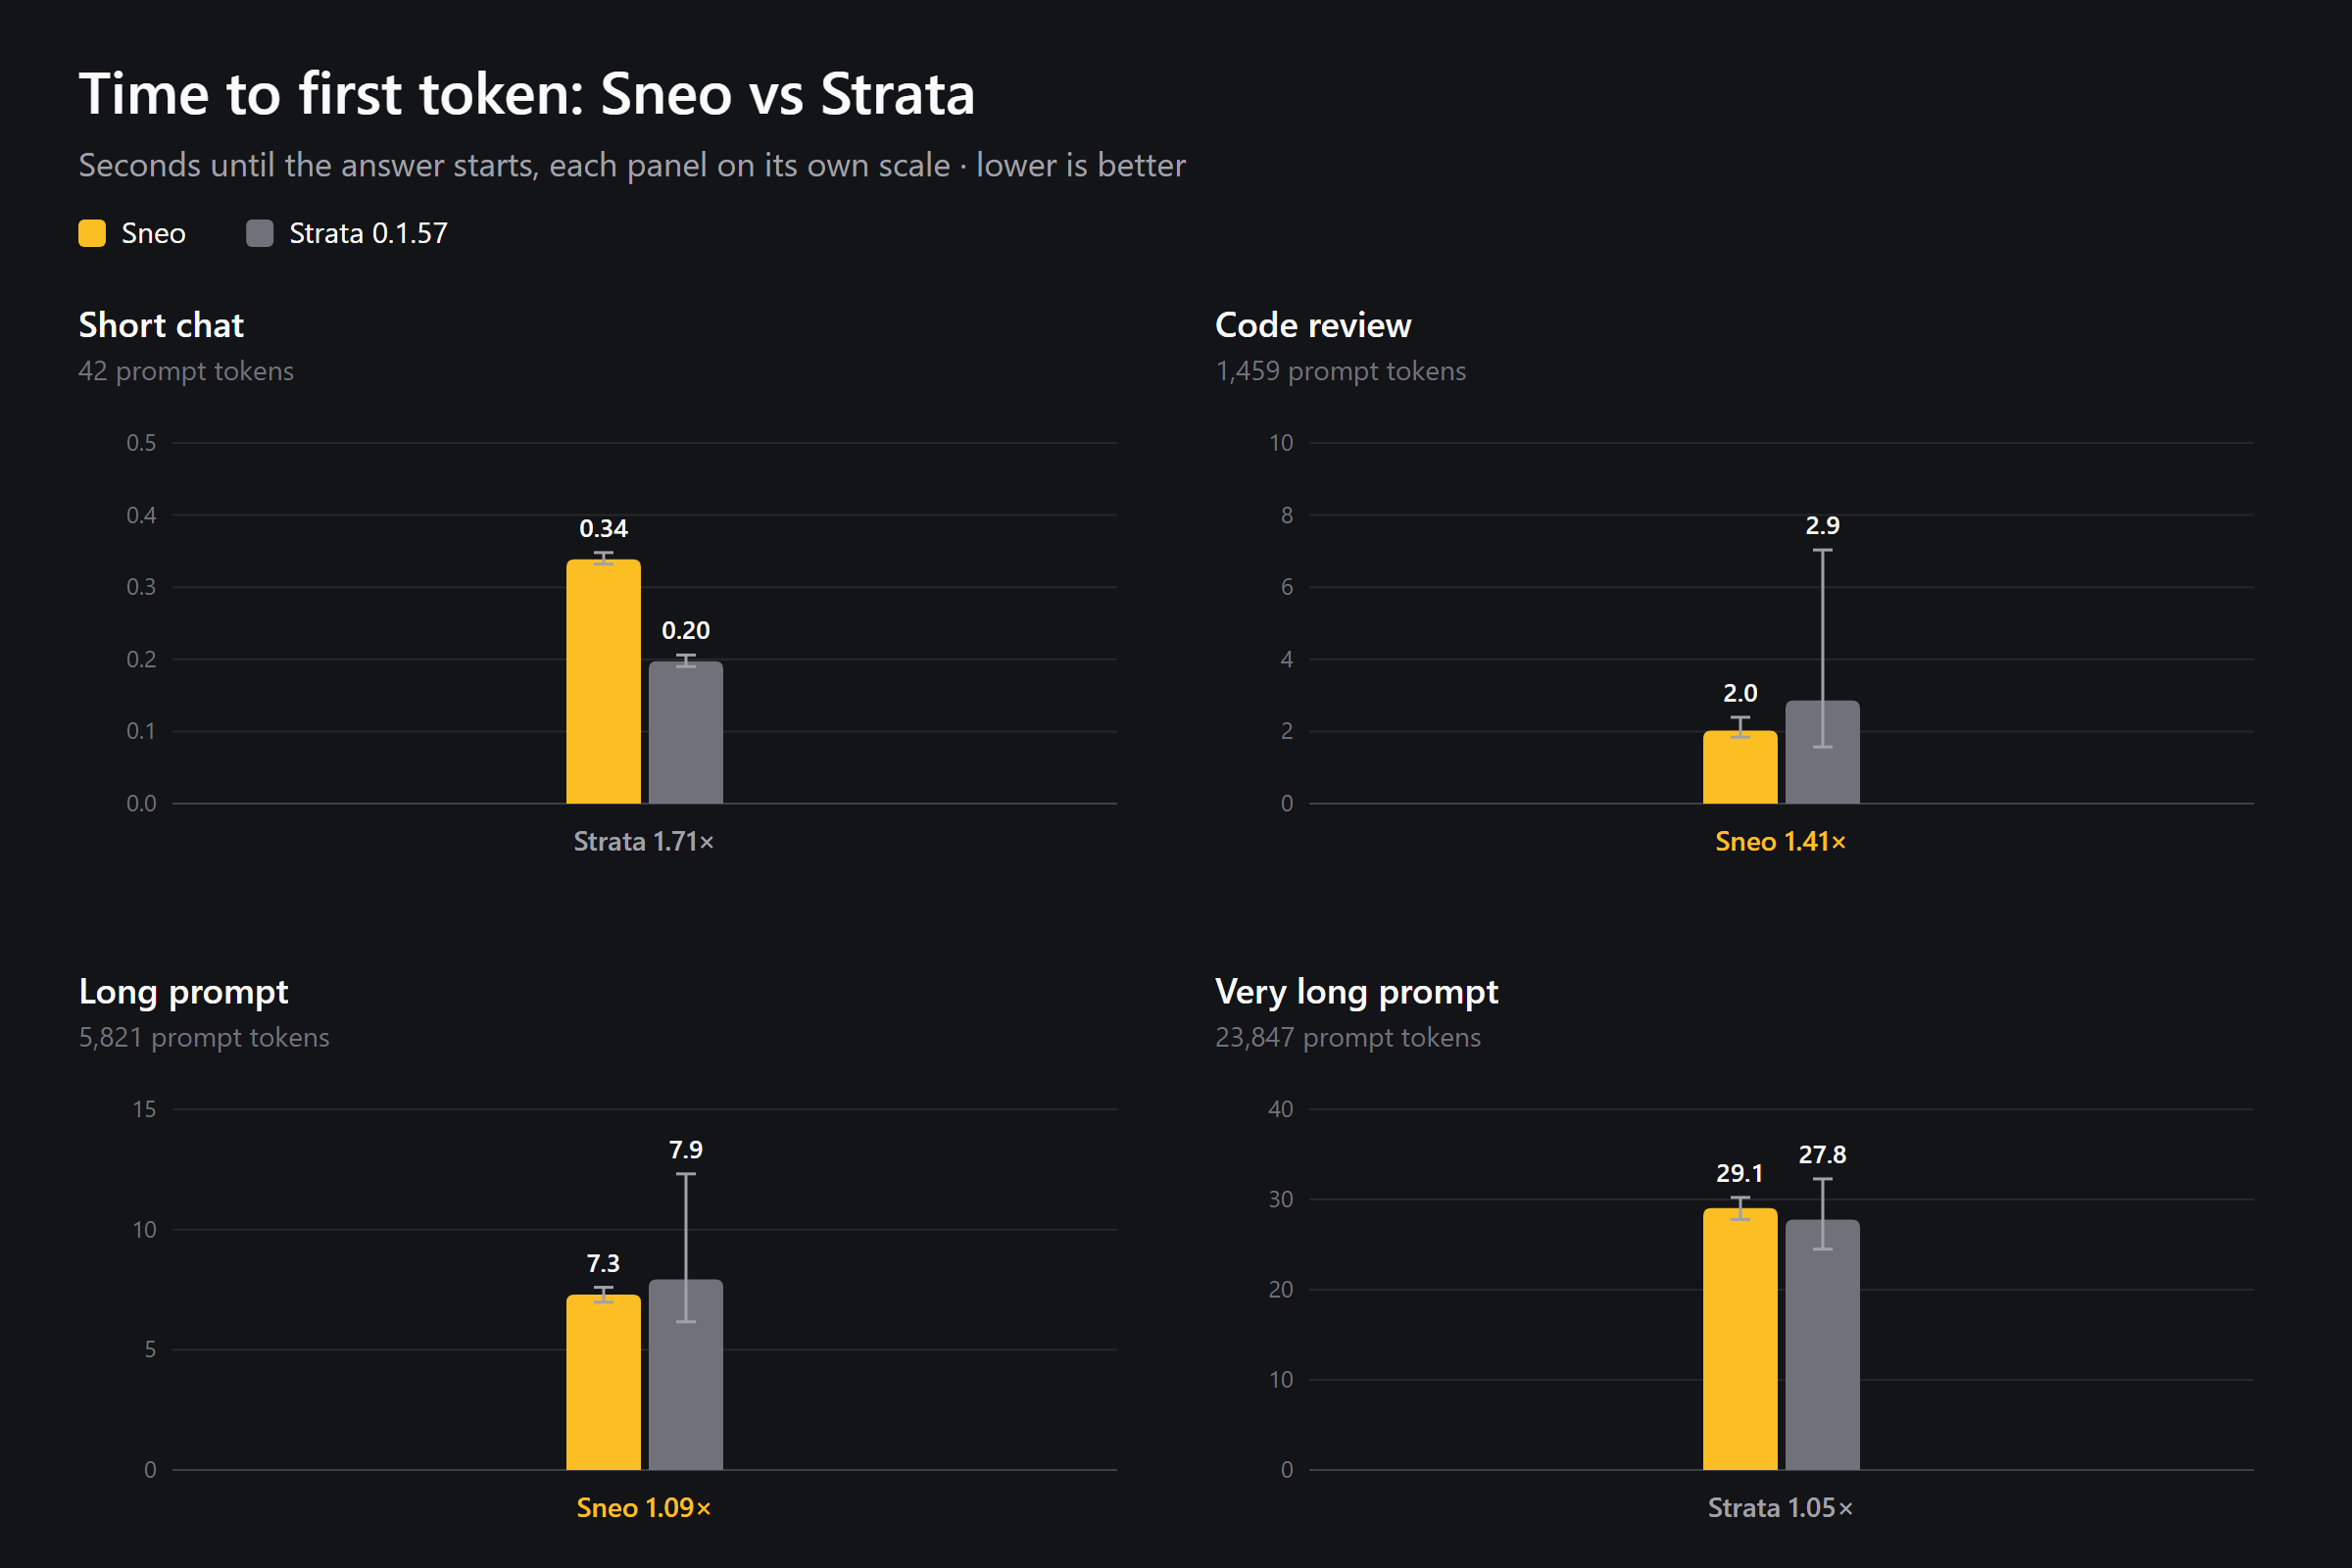
One PC and the same Qwen3.8-Flash-Next IQ3_XXS files, 70.6 GB, with a 64K context window. Sneo ran on the RTX 3090 alone, with its GTX 1070 helper switched off. Strata used the settings of its own app, with the experts kept in RAM.
Thinking on, temperature 0.6, top_p 0.95, top_k 20, up to 256 tokens per answer and a fresh prompt every time. The engines took turns on the GPU, Sneo, Strata, Sneo, Strata, four requests for each prompt size.
Each column is the median of four runs and the thin line goes from the slowest to the fastest one. The line under each group says which engine was faster and by how much.
Measured on Nov 12, 2026 on the main test PC: RTX 3090 24 GB, Intel i9-12900K, 32 GB DDR5, NVMe SSD, Windows 10.
Two cards, from 8 to 24 GB of VRAM
Main test PC
Older card
Speeds are tokens per second while writing. The GTX 1070 was measured with an earlier build of Sneo, and models bigger than VRAM and RAM together read the rest from the SSD as they run.
What makes it fast
Experts where they count
A heat map learns which experts each model calls most and keeps them in VRAM. The rest wait in RAM, and the CPU works on them in step with the GPU.
Guesses ahead
The model's own draft layer proposes the next tokens, and text the answer repeats is copied straight from the prompt. One pass checks them all.
Reads long prompts fast
Tensor core kernels and streamed expert blocks read a 24,000 token prompt in under 30 seconds.
Pool your PCs
Join a second PC over your network or Tailscale and let it hold part of the model with its own memory.
Recipes
Save your tuned settings and heat map in one file. Share it, or import one made on another PC for the same model.
Agent included
The desktop app comes with a coding agent that reads, edits and runs your projects, plus OpenAI and Anthropic compatible APIs for your own tools.
Models and hardware
Qwen3.8-Flash-Next
Qwen3.6-35B-A3B
Sneo for Windows
Install it, pick a model from the built in catalog and start. Sneo sizes VRAM and RAM for your PC on its own.
Download for WindowsWindows 10 or 11 · NVIDIA GTX 10 series or newer · 32 GB of RAM